Model

Multimodal Large Language Model

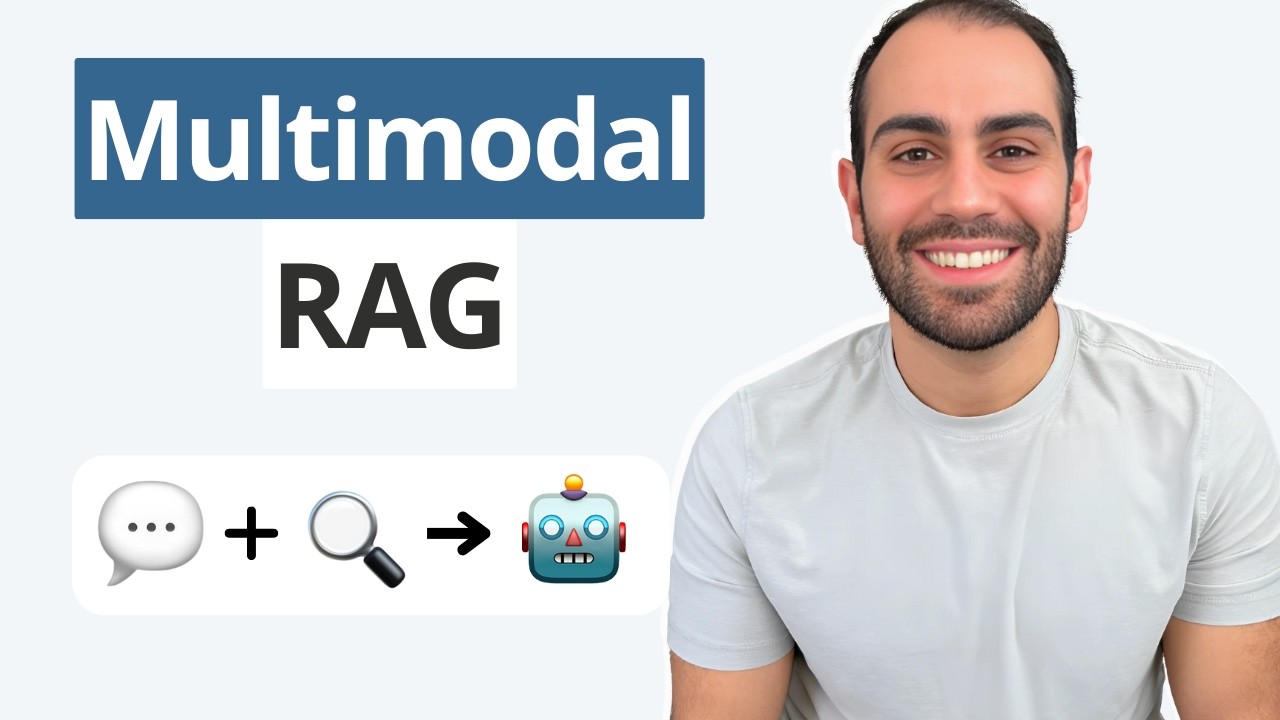
Multimodal Large Language Models are designed to understand and generate text, images, and audio simultaneously, broadening the capabilities of traditional AI. These models, like GPT-5 and Gemini, offer novel ways to interact with AI, allowing for richer content generation and problem-solving. Videos often cover how to implement multimodal embeddings, beginner-friendly guides with Python, and the intriguing ways these models perceive and interpret information.

Also called: Multimodal Large Model
Stop watching · start building
Matched to Multimodal Large Language Model

Makers residency 4th edition

Your idea can be anything. At our last workshops, people built plant-based nutrition businesses, a way to measure planetary resilience, crochet headwear and a way to connect lonely people living in the same building. An asset manager went on to raise an additional £25M on their fund within nine months. The fourth workshop is a full day at KOKO with Nick Sarafa, learning to build with Claude Code. Bring the thing you keep meaning to start. We’ll bring the pizza.

◆ Fri 13 Nov 2026 ◆ KOKO, London
Makers residency 4th edition
Live event
Makers residency 4th edition
Fri 13 Nov 2026
People watching Multimodal Large Language Model also follow
The whole library, sorted

Browse by
topic.

CHOOSETO Studio

What would this save you every week?

Let us build it for you. Design and engineering from the people who shipped platforms to billions of users. AI-native, live in weeks, and yours outright at the end.